Paper Review
xPress: Parallel Refinement for Diffusion Drafters in Speculative Decoding
Block-diffusion drafters sample every position from its own marginal, so a draft block is individually likely but jointly improbable; xPress adds a low-rank causal refiner that reconciles the whole block through parallel Jacobi iterations, lifting acceptance length from 6.25 to 8.02 tokens.
블록 디퓨전 드래프터는 각 위치를 자기 주변분포에서 독립적으로 뽑기 때문에 블록이 개별적으로는 그럴듯해도 결합적으로는 있을 법하지 않다. xPress는 저랭크 인과 리파이너를 얹어 블록 전체를 병렬 Jacobi 반복으로 화해시키고, 수용 길이를 6.25에서 8.02 토큰으로 끌어올린다.
Background Speculative decoding has a small drafter write several tokens ahead and a large target model verify them in one pass, so the ceiling on speedup is set by how many tokens get accepted per round. A recent line replaces the autoregressive drafter with a block-diffusion model that emits a whole block in a single forward pass. Drafting latency drops sharply — and a new problem arrives with it.
배경 추측 디코딩은 작은 드래프터가 여러 토큰을 미리 쓰고 큰 타깃 모델이 한 번에 검증하는 구조로, 속도의 상한은 결국 한 번에 몇 토큰이 수용되는가로 결정된다. 최근 계열은 드래프터를 자기회귀 모델 대신 블록 디퓨전 모델로 바꿔서, 블록 전체를 한 번의 forward로 병렬 생성한다. 드래프팅 지연이 극적으로 줄어드는 대신 새로운 문제가 따라온다.
Problem The final denoising step of a block-diffusion drafter samples each position conditionally independently from its own logit distribution. The resulting block is therefore not a sample from a joint distribution but a collection of per-position marginals. The verifier does the opposite: it scores token k conditioned on the tokens before it. Sequences that are individually likely yet jointly improbable follow, and the early rejections they trigger put a ceiling on acceptance length.
문제 블록 디퓨전 드래프터의 마지막 디노이징 단계는 각 위치의 로짓 분포에서 토큰을 조건부 독립으로 샘플링한다. 그래서 나온 블록은 결합분포에서 뽑은 표본이 아니라 위치별 주변분포의 모음이다. 검증자는 정반대로 동작한다 — k번째 토큰을 앞선 토큰들에 조건부로 평가한다. 개별적으로는 그럴듯한데 함께 놓으면 있을 법하지 않은 수열이 만들어지고, 조기 거절이 수용 길이의 천장을 만든다.
Prior limitations Two families tried to fix this, both at a real cost. One bakes intra-block causality into the draft model itself, which requires retraining the drafter from scratch. The other attaches a small corrective head that runs sequentially — reintroducing exactly the seriality that parallel drafting was adopted to remove. The option that restores causality while keeping parallelism was the empty one.
기존 한계 이 결함을 고치려는 시도는 두 갈래였고 둘 다 대가가 크다. 하나는 드래프트 모델 자체에 블록 내 인과성을 심는 방향으로, 드래프터를 처음부터 다시 학습시켜야 한다. 다른 하나는 순차적으로 도는 작은 보정 head를 붙이는 방향인데, 병렬 드래프팅을 도입한 이유였던 그 직렬성을 되돌려놓는다. 병렬성을 지키면서 인과성을 회복하는 선택지가 비어 있었다.
Goal Recover the mutual dependencies inside a block — and with them acceptance length — without retraining the drafter and without bringing back a token-by-token loop. The constraint is explicit: the added computation must not make drafting the bottleneck again.
목표 드래프터를 재학습하지 않고, 토큰 단위 순차 루프도 다시 들이지 않으면서, 블록 내부의 상호 의존을 복원해 수용 길이를 늘리는 것. 조건은 명확하다 — 추가되는 계산이 드래프팅을 다시 병목으로 만들 만큼 커서는 안 된다.
Method Rather than replacing the drafter logits, xPress adds a per-position logit bias δ: `p = softmax(s + δ)`. The refiner runs in four stages — Fuse (project token embeddings, hidden states and a block summary into a low-rank space), Mix (strictly lower-triangular causal mixing), Trans (residual MLP in that low-rank space), and Read (emit vocabulary-sized corrections). Everything passes through rank r=256, so the cost is that of re-ranking the handful of candidates the drafter already favors, not rescoring the full vocabulary.
방법 드래프터의 로짓을 갈아치우지 않고 위치별 로짓 바이어스 δ를 더한다: `p = softmax(s + δ)`. 리파이너는 네 단으로 구성된다 — Fuse(토큰 임베딩·은닉 상태·블록 요약을 저랭크 공간으로 투영), Mix(엄격한 하삼각 인과 혼합), Trans(저랭크 공간의 잔차 MLP), Read(어휘 크기 보정 출력). 전 구간이 랭크 r=256을 통과하므로, 전체 어휘를 다시 채점하는 게 아니라 드래프터가 이미 선호하는 소수 후보를 재정렬하는 비용만 든다.
Key idea δ depends on the preceding tokens, which in turn depend on δ — a circular dependency spanning the block. Instead of resolving it left to right, xPress resolves it by Jacobi decoding: every position updates simultaneously from the previous iteration. Theorem 1 guarantees convergence to the sequential greedy decode within B iterations for block length B, and empirically K≈6 suffices. It is the difference between solving a system of equations by substituting one variable at a time and sweeping all of them together until they agree.
핵심 아이디어 δ가 앞선 토큰들에 의존하는데 그 토큰들 또한 δ에 의존한다 — 블록을 가로지르는 순환 의존이다. 이걸 왼쪽에서 오른쪽으로 푸는 대신 Jacobi 디코딩으로 푼다: 모든 위치가 직전 반복의 값으로부터 동시에 갱신된다. 정리 1은 블록 길이 B 이내에 순차 greedy 디코드와 같은 결과로 수렴함을 보장하고, 실측으로는 K≈6 반복이면 충분하다. 연립방정식을 변수 하나씩 대입해 푸는 대신 전부를 몇 번 되풀이해 동시에 수렴시키는 셈이다.
Validation The setup is a Qwen3-8B target with a block-16 dFlash drafter, evaluated across seven benchmarks spanning math (GSM8K, MATH-500, AIME25), code (HumanEval, MBPP, LiveCodeBench) and chat (MT-Bench). Both regimes are measured — single-batch and vLLM serving with FlashAttention at batch 32 — which matters, because speculative decoding usually gives back much of its advantage as batch size grows.
검증 타깃 Qwen3-8B에 block-16 dFlash 드래프터를 붙인 구성으로, 수학(GSM8K, MATH-500, AIME25)·코드(HumanEval, MBPP, LiveCodeBench)·대화(MT-Bench) 일곱 벤치마크에서 평가한다. 단일 배치와 vLLM 서빙(FlashAttention, 배치 32) 두 체제를 모두 잰다는 점이 중요하다 — 배치가 커지면 추측 디코딩의 이득은 보통 줄어들기 때문이다.
Results Under greedy decoding (T=0), 6.2× speedup over autoregressive decoding at 8.02 tokens of acceptance length, up from 4.9× and 6.25 for the original dFlash. Under sampling (T=1) the gap widens: 5.3× and 6.97 against dFlash at 3.6× and 4.94, an average improvement of 1.29× at T=0 and 1.46× at T=1. The gain survives serving scale: at batch 32, 2.5–3.1× over the autoregressive baseline and 1.2–1.4× over plain dFlash.
결과 탐욕 디코딩(T=0)에서 자기회귀 대비 6.2× 가속, 수용 길이 8.02 토큰 — 원본 dFlash의 4.9× / 6.25에서 올라간 수치다. 샘플링(T=1)에서는 5.3× / 6.97로, dFlash의 3.6× / 4.94 대비 개선폭이 더 크다(T=0에서 평균 1.29×, T=1에서 1.46×). 서빙 규모에서도 살아남는다: 배치 32에서 자기회귀 대비 2.5–3.1×, 순수 dFlash 대비 1.2–1.4×.
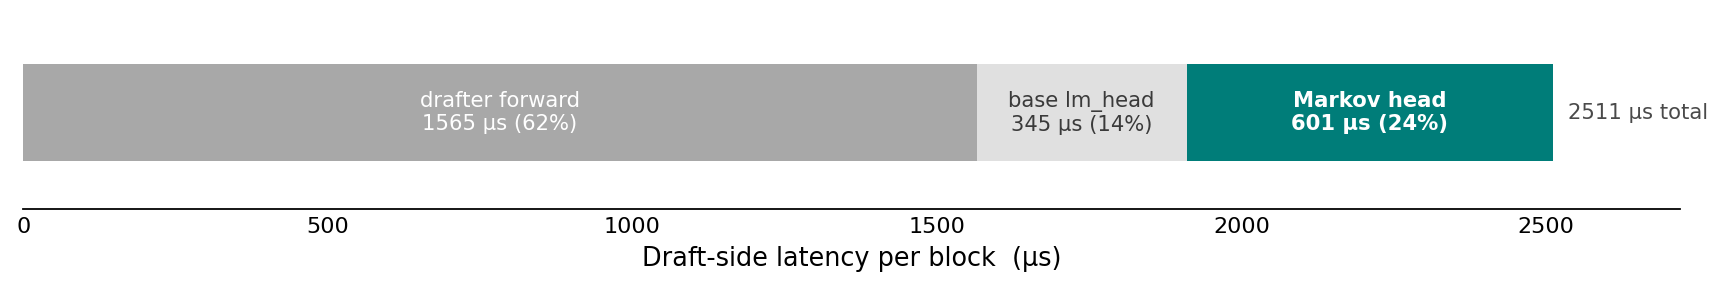
Comparison The sharpest comparison is against a sequential Markov head of the DSpark family. xPress leads on acceptance length across every benchmark while running at far lower latency — 379μs of added drafting time at K=4 iterations, 1.6× faster than the Markov head. The cost gap comes from structure: the linear Fuse-Mix composition folds into precomputed operators, so each iteration costs a single matrix multiplication.
비교 DSpark 계열의 직렬 Markov head가 가장 직접적인 비교 대상이다. xPress는 전 벤치마크에서 수용 길이가 앞서면서 지연은 훨씬 낮다 — K=4 반복 기준 드래프팅 추가 비용 379μs로 Markov head보다 1.6× 빠르다. 선형인 Fuse-Mix 합성이 미리 계산된 연산자로 접히기 때문에 반복당 행렬 곱 한 번이면 된다는 점이 이 비용 차이의 출처다.
Significance Read through an efficiency lens, the contribution is a relocation of where causality is paid for. Instead of putting it in the drafter weights (retraining) or in a sequential head (seriality), xPress puts it in a thin post-hoc stage that converges in parallel. Verification cost is untouched and only the joint quality of the draft improves, which also means the method drops onto existing dFlash checkpoints as they are.
의의 효율 관점에서 이 논문의 값어치는 어디에 인과성을 넣을 것인가를 재배치했다는 데 있다. 인과성을 드래프터 가중치(재학습)나 순차 head(직렬성)에 넣는 대신, 병렬로 수렴하는 얇은 후처리에 넣었다. 검증 비용은 그대로 두고 드래프트의 결합 품질만 올리는 개입이라, 기존 dFlash 체크포인트에 그대로 얹을 수 있다는 실무적 의미도 크다.
Limitations The authors state no separate limitations section in the sections retrieved — not stated in the paper. Two exposed points: the target is a single model family (Qwen3-8B), and because the refiner reads the drafter hidden states, a change of drafter architecture appears to require retraining it (reviewer judgment). Theorem 1 guarantees the greedy path, so convergence behaviour under temperature sampling rests on the empirical K≈6 rather than on the bound (reviewer judgment).
한계 가져온 절에서 저자들이 별도의 한계 절을 두지 않았다 — 논문 내 명시 없음. 눈에 띄는 미검증 지점은 타깃이 Qwen3-8B 한 계열이라는 것과, 리파이너가 드래프터 은닉 상태를 읽으므로 드래프터 아키텍처가 바뀌면 재학습이 필요해 보인다는 점이다(리뷰어 판단). 정리 1의 보장은 greedy 경로에 대한 것이라 온도 샘플링에서의 수렴 성질은 실측 K≈6에 기대고 있다(리뷰어 판단).
Future work Not stated in the paper. The natural continuations are how far one refiner transfers across drafter/target pairings, and whether K can be adapted downward as batch size grows (reviewer judgment).
향후 과제 논문 내 명시 없음. 자연스러운 연장선은 리파이너를 드래프터·타깃 조합 사이에서 얼마나 옮겨 쓸 수 있는지, 그리고 배치가 더 커질 때 K를 적응적으로 줄일 수 있는지다(리뷰어 판단).
Released resources No public release verified — no code or checkpoint release could be confirmed from the paper. The arXiv abstract and PDF are the only verified primary sources.
자원 공개 공개 링크 확인 안 됨 — 논문에서 코드나 체크포인트 공개를 확인하지 못했다. arXiv 초록과 PDF만 확인된 1차 출처다.
The research thread
Where this paper sits 연구의 흐름
This paper stands on the block-diffusion drafter line, which began from the observation that the bottleneck in speculative decoding is not the drafter's *quality* but the drafter's *latency*. An autoregressive drafter spends one forward pass per token; a block-diffusion drafter emits the whole block at once. The trade worked — and the price was the causal structure inside the block.
Most of what followed has been the story of buying that causality back. Some work retrained the drafter to bake it into the architecture, some routed around it with conditional tree drafting, some bolted a small sequential head onto the end. Each paid in retraining cost or in seriality. What xPress changes is not *where* causality sits but *how the dependency is solved* — a circular dependency that looks like it demands a sequential pass is instead solved in parallel by fixed-point iteration.
If the move holds, it opens two questions. The first is how far a thin parallel refiner transfers across drafter/target pairings — if the refiner is genuinely modular, it need not be trained per checkpoint. The second concerns the serving regime, where growing batch size makes drafting, not verification, expensive again: is there a schedule that adapts the iteration count K downward? K is a fixed constant today, and the amount of reconciliation a block actually needs surely varies from block to block.
이 논문은 블록 디퓨전 드래프터 계보 위에 서 있다. 그 계보는 추측 디코딩의 병목이 드래프터의 *품질*이 아니라 드래프터의 *지연*이라는 관찰에서 출발했다. 자기회귀 드래프터는 토큰 하나마다 forward를 한 번씩 쓰는데, 블록 디퓨전 드래프터는 블록 전체를 한 번에 낸다. 그 교환은 성립했지만, 대가로 블록 내부의 인과 구조를 잃었다.
그 이후의 작업들은 대체로 잃어버린 인과성을 되사오는 이야기였다. 어떤 것은 드래프터를 다시 학습시켜 구조 안에 심었고, 어떤 것은 조건부 트리 드래프팅으로 우회했고, 어떤 것은 작은 순차 head를 뒤에 달았다. 각각은 재학습 비용이나 직렬성이라는 값을 치렀다. xPress가 바꾸는 지점은 인과성의 *위치*가 아니라 인과성을 *푸는 방식*이다 — 순차적으로 풀어야 할 것처럼 보이는 순환 의존을, 고정점 반복으로 병렬로 푼다.
이 수가 통한다면 열리는 질문은 두 방향이다. 하나는 얇은 병렬 정제가 드래프터-타깃 조합을 얼마나 넘나들 수 있는가 — 리파이너가 진짜로 모듈이라면 체크포인트마다 따로 학습할 필요가 없어진다. 다른 하나는 배치가 커질수록 검증이 아니라 드래프팅이 다시 비싸지는 서빙 체제에서, 반복 횟수 K를 적응적으로 줄이는 스케줄이 성립하는가다. 지금은 K가 고정 상수인데, 블록마다 필요한 화해의 양은 분명 다를 것이다.
Sparks — where one could take this 아이디어의 씨앗
-
Theorem 1 bounds convergence by the block length B, yet practice stops at K≈6. If the iterations a given block actually needs could be predicted and cut short, how much of the remaining drafting cost would disappear? 정리 1은 블록 길이 B 이내 수렴을 보장하지만 실측은 K≈6에서 멈춘다. 블록마다 필요한 반복 수를 미리 예측해 조기 종료하는 기준이 있다면, 남은 드래프팅 비용은 얼마나 더 줄어들까?
-
Reading the drafter's hidden states ties the refiner to that drafter. How much would a variant that reads only the logits give up, and how much portability would it buy in exchange? 리파이너가 드래프터의 은닉 상태를 읽는다는 건 드래프터에 묶여 있다는 뜻이다. 은닉 상태 대신 로짓만 읽는 변형은 얼마나 손해를 보고, 그 대가로 얼마나 이식성을 얻을까?
-
The advantage persists at batch 32 but narrows. Decomposing whether verification or drafting is what erodes it as batch size grows would decide where the next intervention belongs. 수용 길이는 배치 32에서도 이득이 남지만 폭은 줄어든다. 배치가 커질 때 이득을 갉아먹는 것이 검증 쪽인지 드래프팅 쪽인지 분해해보면, 다음 개입 지점이 어디인지가 갈릴 것이다.
Seeds grounded in the paper's own stated limitations and open questions. 논문이 스스로 밝힌 limitations와 open questions에 뿌리를 둔 씨앗입니다.
Notes
Notes
Linked reviews
DSpark: Confidence-Scheduled Speculative Decoding with Semi-Autoregressive Generation
A semi-autoregressive drafter combined with confidence-scheduled verification fixes the intra-block acceptance decay of parallel speculative-decoding drafters, delivering 51-85% throughput and latency gains in DeepSeek-V4 production serving.
speculative-decodingDominoTree: Conditional Tree-Structured Drafting with Domino for Speculative Decoding
A training-free best-first draft-tree method scores candidate tokens using a released drafter's path-dependent causal correction instead of treating positions as independent, reaching up to 6.6x speedup and the highest reported mean accept length on Qwen3-4B.
speculative-decodingAngelSpec: Towards Real-World High Performance Inference with Speculative Decoding
AngelSpec unifies two rival speculative-decoding drafter families -- lightweight autoregressive Multi-Token-Prediction heads and block-parallel diffusion drafters -- by co-specializing each one's training data to the workload it is actually good at, upgrading the diffusion drafter's architecture (DFly), and letting a batch-level scheduler (D-cut) reallocate verification budget online; on Tencent's own Hy3 MoE model family this reaches a 1.98-2.40x speedup over autoregressive decoding, validated against live production traffic rather than a static benchmark.
kv-cacheWindowed-MTP: Removing the Full-Context Draft-KV Tax at Million-Token Context
Windowed-MTP names the long-context draft-attention tax in built-in Multi-Token-Prediction speculative-decoding heads -- the draft re-reads the entire KV cache every step, so at million-token context it can flip speculation net-negative -- and fixes it losslessly with a training-free sink+window applied only to the draft's attention, cutting per-decode-step cost 28-44% across three architecture families at 1M tokens.
speculative-decodingAdaFlash: Adaptive Speculative Decoding via On-Policy Distilled Diffusion Drafters
AdaFlash stabilizes diffusion-model drafters for speculative decoding, whose bidirectional attention otherwise causes high acceptance-rate variance across domains and token positions, via on-policy reverse-KL distillation plus an adaptive candidate-length head, reaching up to about 66% higher throughput in high-concurrency serving.
speculative-decodingStrong Drafts Need Compact Memories: Long-Context Speculative Decoding with Compressed KV Cache
Gives an independent speculative-decoding drafter a compressed KV memory instead of a full cache, so it keeps the acceptance rate of a strong drafter without its KV-access cost growing with context length.